8 min read · October 15, 2026
Solving Tech Snags: Practical steps for Helsinki-focused updates
7 min read · Updated: 2026-10-15
Tech readers often face gaps when local information feeds crash or misaligns with real-world workflows. This article translates a problem into a practical, repeatable process: how to identify reliable Helsinki data sources, verify their relevance for software decisions, and apply the results without overfitting to noise. You’ll learn a method that keeps your product decisions grounded in solid local signals rather than hype.
First, we’ll map the key needs: what kind of Helsinki data matters for your project, how to spot trustworthy sources, and what simple checks separate signal from noise. Then we’ll share concrete steps to gather, validate, and compare options. The goal is a repeatable approach you can reuse across updates, deployments, or dashboards.
Finally, you’ll see how to weave local Helsinki signals into technical decisions—without overcomplicating your stack. The process emphasizes clarity, reproducibility, and a focus on what your users actually need. Expect concrete examples, practical caveats, and ready-to-use checklists you can adopt now.
- Identify Helsinki data needs and success metrics, then pick a reliable source and verify its quality.
- Choose an integration method that fits your stack, balancing latency and maintenance.
- Diversify sources and maintain governance to avoid missteps and bias.
- Start with a lightweight playbook and build toward repeatable processes across projects.
Basics: framing the problem
Define the data need
Start by naming the exact problem your product must solve with Helsinki data. For example, is a live event feed needed, or a trend analysis from local sensors? Define success metrics in observable terms, such as latency or accuracy, so you can test outcomes later. L1 Helsingin Uutiset Helsinki uutiset is a local news source you may want to monitor for context.
- List the top three data needs for Helsinki tech work.
- Note potential privacy or compliance issues.
- Sketch a minimal test that proves usefulness.
- Record a baseline to compare future changes.
Describe the constraints you face, including privacy, bandwidth, and regional accuracy. Identify which data sources are legally permissible and technically compatible with your stack.
Compare a few candidate sources to see which best matches your core requirements, avoiding sources that add friction or large data costs. This helps keep the project lean and focused on what actually moves the needle.
- Clear data need statements
- Defined success metrics
- Feasible constraints
- Initial source shortlist
- Early test plan
How to verify data quality
Assess reliability and freshness
Reliability comes from consistent availability and predictable performance. Check whether a data stream has occasional outages, and note the typical refresh rate to ensure it matches your use case. A useful resource on this topic: mitä Helsingissä tapahtuu.
Evaluate accuracy by cross-checking with a trusted secondary source or a small, controlled test. If a feed underreports events during peak hours, plan for a fallback.
Document bias risks, such as provider proximity effects or coverage gaps. Acknowledge what the data might miss and how that gaps your decisions.
Embed lightweight monitoring to catch drift early, so you can alert before decisions rely on stale or biased signals.
- Consistency of uptime
- Refresh cadence
- Cross-checks with secondary sources
- Bias awareness
- Lightweight monitoring
What options fit most stacks
Compare integration approaches
Three common routes exist: pull from public APIs, push from event streams, and hybrid approaches with caches. Each has trade-offs in latency, control, and complexity. Pick the route that aligns with your deployment model and team skills. L3 lisää yrityksesi Helsingissä can influence how you target local business tooling and partnerships.
Evaluate the maintenance burden of each option, including API changes, authentication, and rate limits. A simpler integration reduces risk and speeds up iteration.
Prototype with a minimal integration and measure impact on the product’s core metrics. Avoid sprawling integrations that only look good on paper.
Balance speed and reliability by choosing a path that scales with your user load and keeps data governance simple.
- Pull API
- Event stream
- Hybrid with cache
- Prototype first
- Governance considerations
| Method | Pros | Cons |
|---|---|---|
| API pull | Simple to implement | Limited control on data freshness |
| Event stream | Low latency | Higher infrastructure needs |
| Hybrid with cache | Balanced approach | Complex cache invalidation |
Guard against single-source dependence by validating with at least one independent feed.
Pitfalls to avoid
Watch for overfitting to local signals
It can be tempting to tailor data to a single city or noise pattern. Overfitting harms generalizability and may mislead product decisions when user distribution changes. L4 avoimet työpaikat Helsingissä would matter if you are staffing a Helsinki-based data team, especially for security and DevOps roles.
Guard against single-source dependence by validating with at least one independent feed. Diversification reduces risk of outages and bias.
Keep data governance transparent: who can access data, how it’s stored, and how it’s used. Clear policies prevent missteps and rebuild trust.
Regularly revisit assumptions as the product evolves, ensuring Helsinki signals remain relevant to a broader user base.
- Overfitting risk
- Need for multiple sources
- Clear governance
- Ongoing assumption review
Security safeguards and privacy considerations
Protecting data at rest
Begin with strong encryption and access controls to minimize exposure if a system is compromised. Use role-based permissions to limit who can view sensitive Helsinki data and audit every change. Regularly review keys and rotate credentials to close gaps before they become problems. kuolinilmoituksen julkaiseminen Helsingissä
- ☐ Define a clear data retention policy and apply it consistently across teams.
- ☐ Regularly test incident response drills to ensure readiness.
- ☐ Document who can approve data sharing and how it is approved.
- ☐ Keep an up-to-date inventory of data assets and their protections.
Implement layered security so a breach in one area does not cascade. Encrypt backups separately and store them offline where feasible. Apply least-privilege principles to administrative accounts and enforce multi-factor authentication for critical tools.
Keep privacy impact assessments up to date as data workflows evolve. Document data sources, purposes, and retention periods to justify what you collect. Align practices with local regulations and internal policy to avoid surprises during audits.
- Enforce MFA for admin access
- Limit data access by role
- Regularly rotate credentials
- Encrypt backups and sensitive fields
Scaling Helsinki data work
Optimizing data pipelines
Design pipelines with modular stages so updates to one part don’t disrupt others. Use streaming for near-real-time Helsinki feeds and batch for historical checks to balance latency and cost. Keep transformations simple and well-documented.
Profile pipeline throughput and set realistic SLAs so teams know when to expect results or raise flags. Use idempotent steps to avoid duplicate processing. Monitor dashboards should alert on anomalies rather than silence.
Document failure modes and recovery steps so any operator can recover quickly during outages. Maintain versioned configs to replay past runs for audits. Plan capacity with room to grow as data sources expand.
- Modular pipeline stages
- Streaming for live data
- Idempotent processing
- Versioned configurations
- Operational dashboards
User-centric data visualization
Designing for clarity
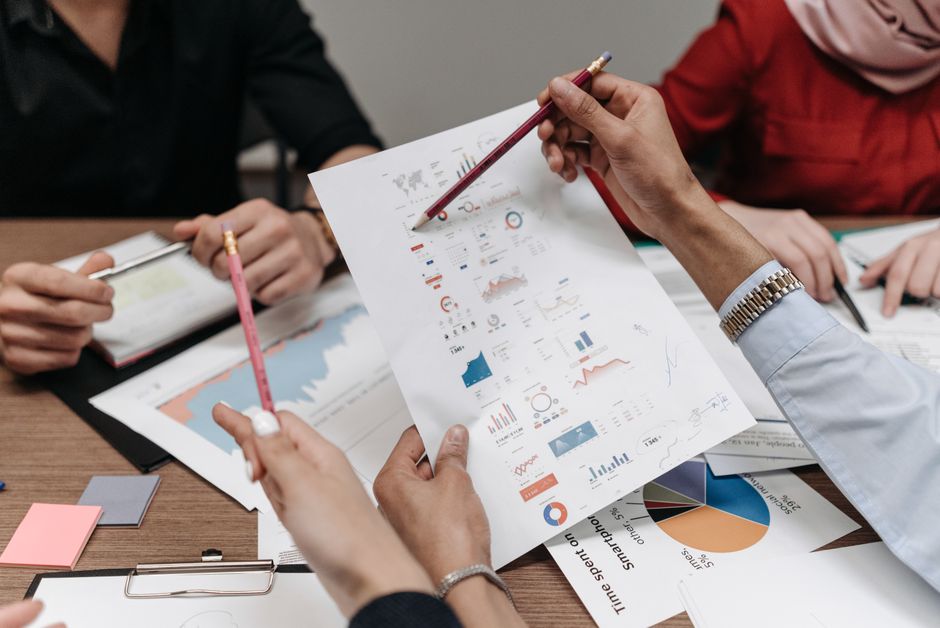
Start with a clear hypothesis about what Helsinki users need to know. Use simple color palettes and consistent typography to reduce cognitive load. Include labels and legends directly on visuals to minimize guesswork.
Structure dashboards around tasks rather than data points so readers can answer specific questions quickly. Provide drill-down paths for analysts who need deeper context. Validate charts with real users and iterate based on feedback.
Ensure accessibility by testing color contrast and keyboard navigation. Offer alternate text for images and supportive transcripts for charts. Keep layouts responsive so critical insights stay visible on different devices.
- Task-focused layouts
- Accessible visuals
- Consistent styling
- Iterative user testing
Automation and CI for data pipelines
Integrating tests and deployment
Embed data validation tests in the CI pipeline to catch anomalies before they reach production. Use lightweight unit checks for schema compliance and end-to-end tests for critical Helsinki data flows. Automate failing builds to force quick fixes.
Automate deployment of configuration changes alongside code to keep environments in sync. Use feature flags to roll out changes gradually and monitor impact. Maintain a rollback plan in case a deployment introduces breaking changes.
Document test coverage and failure rates so teams know where to improve. Keep test data isolated from production sources to protect privacy. Schedule regular dry runs of deployments to practice recovery and minimize downtime.
- Schema and integrity tests
- Feature flags for gradual rollout
- Rollback plans
- Isolated test data
- Regular deployment rehearsals
Frequently asked questions
How should a Helsinki data update inform software teams?
Provide a concise summary of data changes, the sources, and the potential impact on applications. Include a quick health check and any known limitations, so developers know what to expect and where to watch for anomalies.
What steps safeguard user privacy in Helsinki-focused datasets?
Apply least-privilege access, anonymize sensitive fields where possible, and keep data access logs. Regularly review data flows for potential re-identification risks and adjust retention policies accordingly.
How can teams scale data workflows without sacrificing quality?
Automate validation at every stage, implement modular pipelines, and monitor metrics that matter to users. Use versioning for configurations and keep rollback plans ready in case of failures.
What mistakes commonly derail Helsinki data projects?
Overlooking data provenance, skipping tests, and failing to coordinate across teams. Start with a minimal viable data path and add checks before expanding to new sources.
Specific closing H2
The workflow improvements outlined here give teams a practical route from problem framing to production-ready pipelines, with Helsinki-specific context guiding choices.
With security, scalability, and user experience in mind, implement changes in small, auditable steps and measure impact before expanding to new data sources.